Jordan Butler · 23 October 2026
Adapting Modular Architectures to Handle Exponential Data Growth in Financial Forecasting Systems
Financial institutions face mounting pressure from exponential data growth that stems from high-frequency trading records, alternative data feeds, and regulatory reporting requirements, yet modular architectures offer a structured path forward by breaking systems into independent, scalable components that handle increasing volumes without full redesigns, and observers note this approach gained traction as data inflows accelerated through 2025 into October 2026.
Understanding Modular Architectures in Forecasting Contexts
Modular architectures divide forecasting platforms into discrete services such as data ingestion layers, processing engines, model training modules, and output visualization tools, each operating with defined interfaces that allow isolated updates or expansions, and research from institutions like the European Central Bank shows these designs reduce downtime during scaling events compared to monolithic setups that require complete rebuilds when data thresholds are crossed.
Teams implement these structures through microservices and container orchestration platforms that assign resources dynamically, which means a surge in market sentiment data from social sources can trigger additional processing nodes without affecting core valuation models, while data from the Bank for International Settlements indicates global financial entities reported average data volume increases of 35 percent annually in recent cycles.
Drivers of Exponential Data Expansion
Real-time transaction streams, satellite imagery for supply chain predictions, and sensor data from supply networks contribute to the surge, and analysts track how these inputs multiply forecasting complexity because traditional systems struggle to ingest and clean datasets that double every few months, whereas modular designs isolate the ingestion service to apply parallel filtering techniques that maintain throughput.
Regulatory mandates in multiple jurisdictions further amplify requirements by demanding granular audit trails and scenario testing outputs, which adds structured yet voluminous records that forecasting engines must incorporate, and studies from the US Federal Reserve highlight how compliance data volumes alone grew substantially between 2023 and 2026.
Strategies for Scaling Modular Components
One effective tactic involves deploying elastic compute resources that activate based on queue lengths in data pipelines, allowing the system to expand capacity during earnings season spikes or geopolitical events, and practitioners integrate message brokers to decouple producers from consumers so that downstream models continue operating even when upstream feeds experience latency.
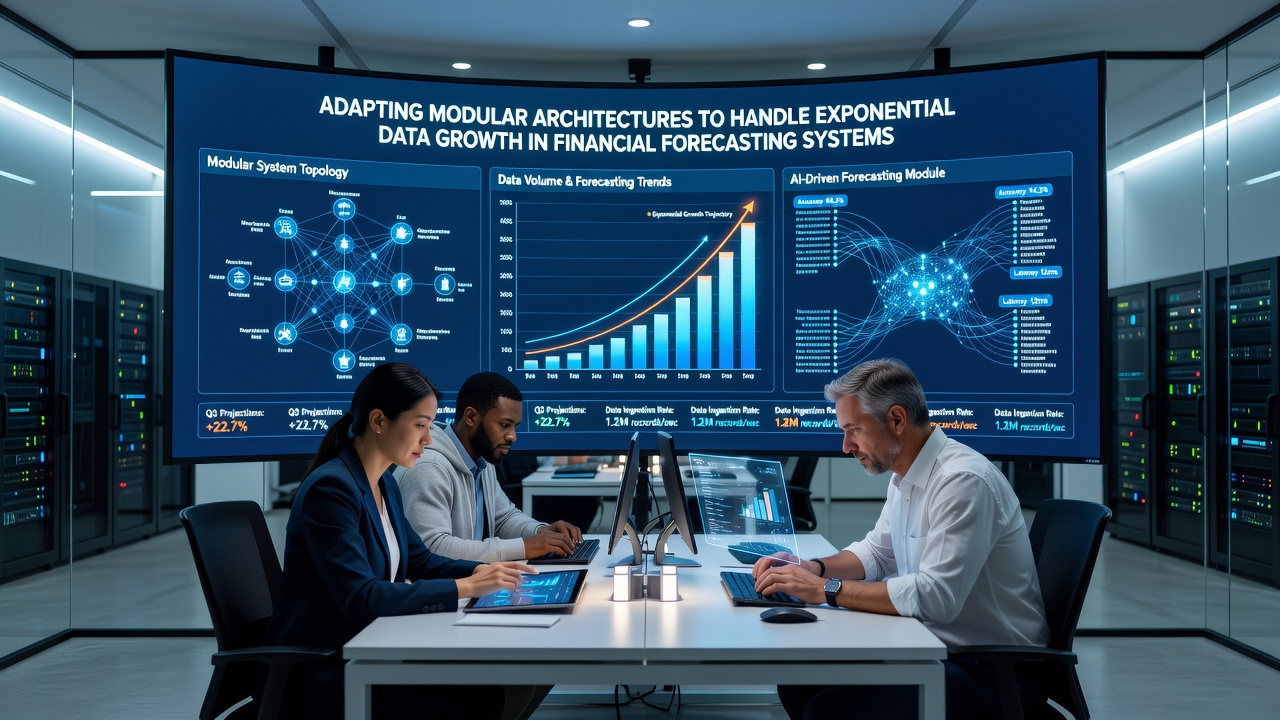
Another method focuses on model partitioning where ensemble techniques split across specialized containers, each trained on subsets of the expanded dataset, and this segmentation supports incremental retraining cycles that avoid full model rebuilds, whereas observers report reduced compute costs in deployments that follow this pattern through October 2026.
Integration of Advanced Processing Techniques
Stream processing frameworks handle continuous data flows by applying windowed aggregations and anomaly detection at the edge before storage, which prevents bottlenecks in central repositories, and organizations pair these with distributed databases that shard records across nodes to support concurrent queries from multiple forecasting teams.
Machine learning pipelines benefit when modular designs incorporate version control for both data schemas and algorithm variants, enabling A/B testing of new prediction methods on live subsets without risking production accuracy, and evidence from academic sources such as reports by the MIT Center for Finance and Policy shows improved adaptability in environments where data characteristics shift rapidly.
Case Examples from Industry Deployments
Take one global bank that restructured its equity forecasting platform by extracting the alternative data ingestion service into a standalone module with auto-scaling triggers, and this change allowed the institution to absorb a fourfold increase in news and sentiment inputs during market volatility periods without interrupting daily forecasts, while similar patterns appear in reports from Canadian regulatory filings on technology upgrades.
Another instance involves an asset management firm that introduced containerized simulation engines for stress testing, each handling distinct asset classes, and the separation permitted parallel execution across cloud regions that aligned with growing regulatory stress scenario libraries, according to industry consortium summaries from the Asia-Pacific region.
Challenges and Mitigation Approaches
Consistency across modules presents ongoing hurdles because data transformations in one service can propagate errors if interface contracts lack strict validation, yet teams counter this through automated testing suites and schema registries that enforce compatibility during deployments, and data indicates these practices lowered integration failures in scaled environments tracked through 2026.
Security considerations also intensify with distributed components because each service expands the attack surface, which prompts adoption of zero-trust networking and encrypted inter-module communication, while auditors from various oversight bodies emphasize the need for centralized logging to maintain traceability across the architecture.
Conclusion
Modular architectures continue to demonstrate their value in financial forecasting by enabling targeted expansions that match data growth trajectories, and organizations that adopt these designs position themselves to integrate emerging data sources efficiently as volumes rise beyond current October 2026 benchmarks, with ongoing refinements in orchestration tools supporting further evolution in processing capabilities.